Selected publications

Research projects

Work on efficient and capable language models, conditional computation, on-device inference, multi-task learning, and computer vision.
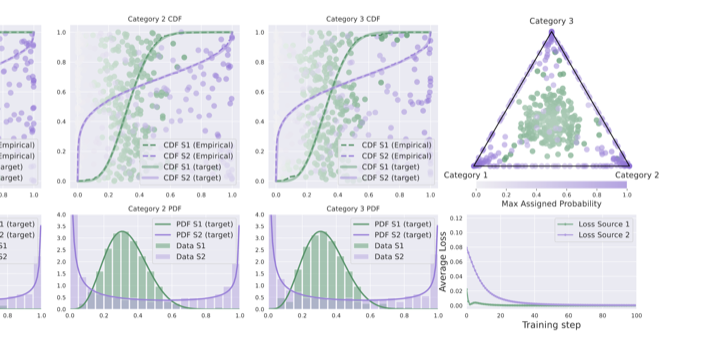
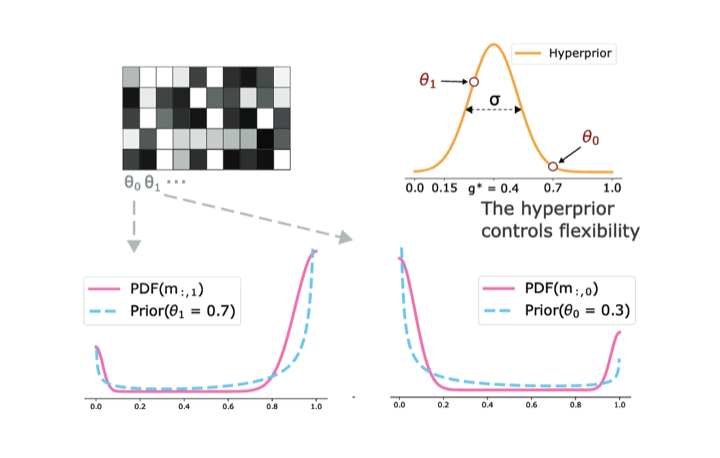
Visualization of Dirichlet-Prior Shaping for expert specialization

Dirichlet-Prior Shaping

ICML 2026

Guiding expert specialization in MoEs via Dirichlet-Prior Shaping (DPSL). DPSL is a powerful tool to instill a wide array of desired statistical properties into the router's behavior.
MoE Dirichlet-Prior Shaping Upcycling Expert Specialization Batch-shaping Loss LLM Efficiency
Efficient reasoning on edge devices project overview

Reasoning on the Edge

Qualcomm AI Research · Technical report 2026

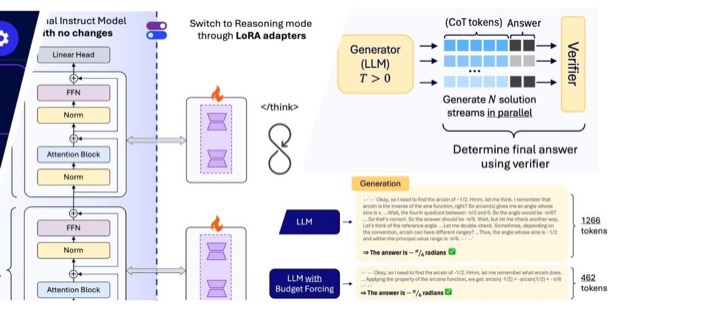
Reasoning in small LLMs using LoRA adapters, combined with supervised fine-tuning and RL-based Budget forcing.
LoRA RL for Budget Forcing Chain-of-thought Model switching Reasoning On-device LLM Efficiency
KaVa compressed KV-cache distillation architecture

KaVa: Latent Reasoning

ICLR 2026

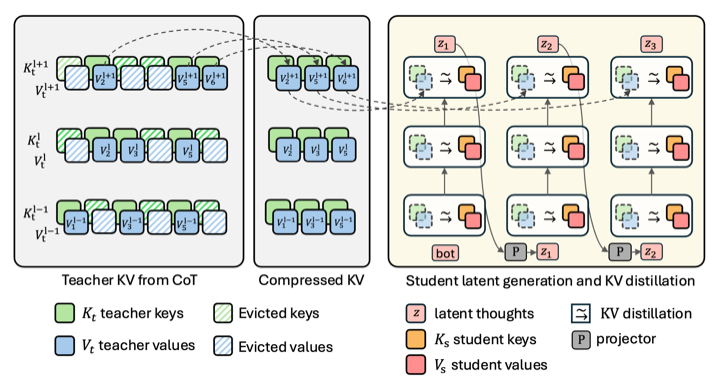
Distilling knowledge from a compressed KV-cache of a teacher into a latent-reasoning student.
Latent Reasoning KV-cache KV-cache distillation Chain-of-thought LLM Efficiency
Cache-MoE expert caching architecture for mobile inference

Cache-MoE

TMLR 2025 · NeurIPS 2024 demo

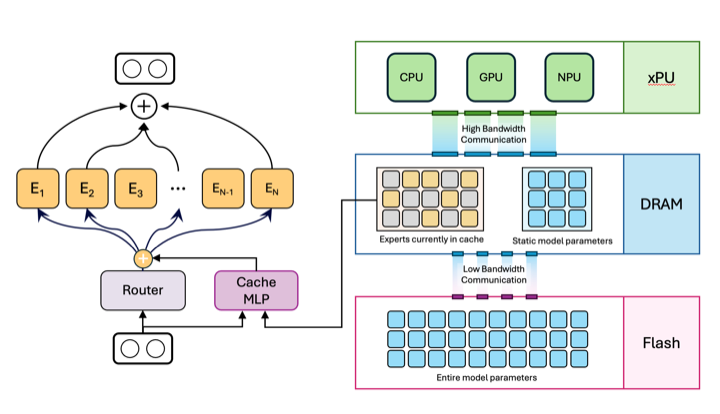
Efficient Mixture-of-Experts for mobile devices with limited DRAM via expert caching.

MoE On-device Caching LLM Efficiency
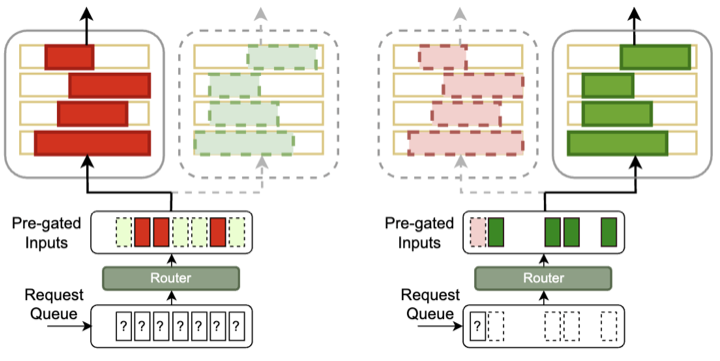
READ-ME router-decoupled mixture-of-experts architecture

Refactor LLM into MoE

NeurIPS 2024

Refactorizing LLMs as router-decoupled mixture of experts with system co-design.

MoE Batched-inference Dynamic sparsity Decoupled routing LLM Efficiency
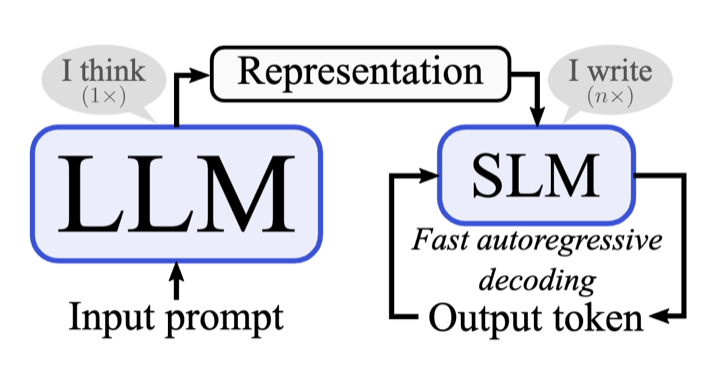
LLM-to-SLM fast autoregressive decoding method

LLM-to-SLM

ICML 2024 · ES-FoMo II workshop

Think Big, Generate Quick: LLM-to-SLM for fast autoregressive decoding.

Hybrid LLM Fast decoding LLM Efficiency LLM to SLM
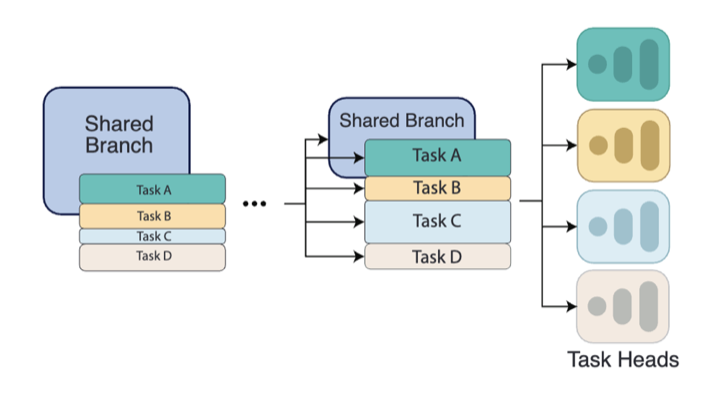
InterroGate representation sharing and specialization method

InterroGate for MTL

BMVC 2024

Learning to share, specialize, and prune representations for Multi-task Learning.
Multi-task Learning Inference efficiency Gated Networks Channel sparsity
Scalarization method for multi-task and multi-domain learning

Scalarization for MTL

NeurIPS 2023

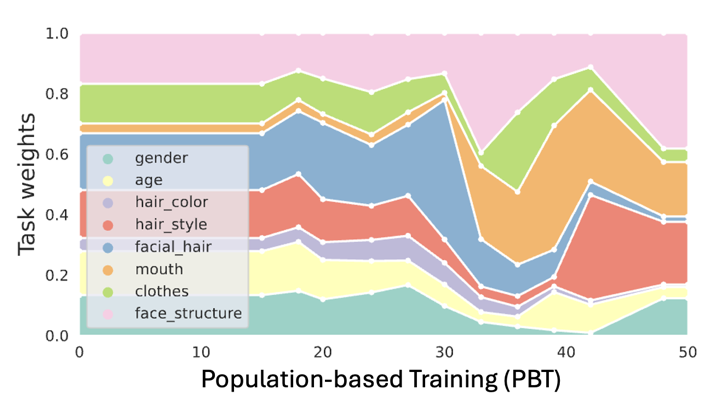
Scalarization for Multi-Task and Multi-Domain Learning at scale.
Population-based Training Scalarization Multi-Task Learning Multi-Domain Learning
MSViT dynamic mixed-scale tokenization examples

MSViT

ICCV 2023 · NIVT workshop

Dynamic mixed-scale tokenization for vision transformers.

Conditional compute Mixed-scale Efficient CV Tokenization
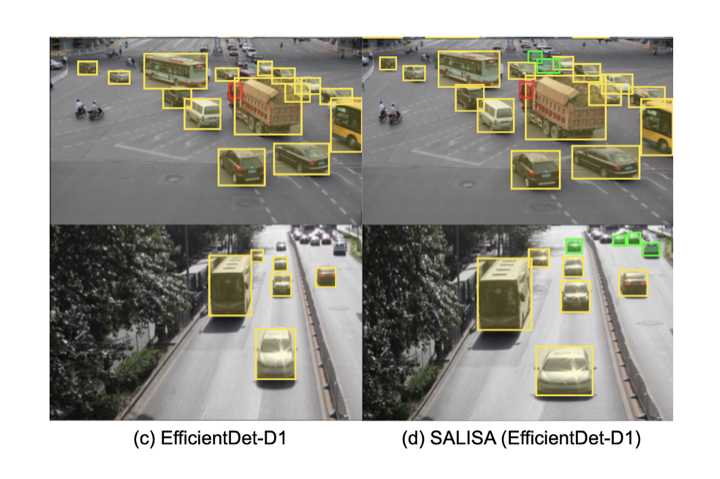
Salisa saliency-based sampling for video object detection

Salisa

ECCV 2022

Saliency-based input sampling for efficient video object detection.

Efficient Inference VOD Video Object Detection Spatial Transformer Network
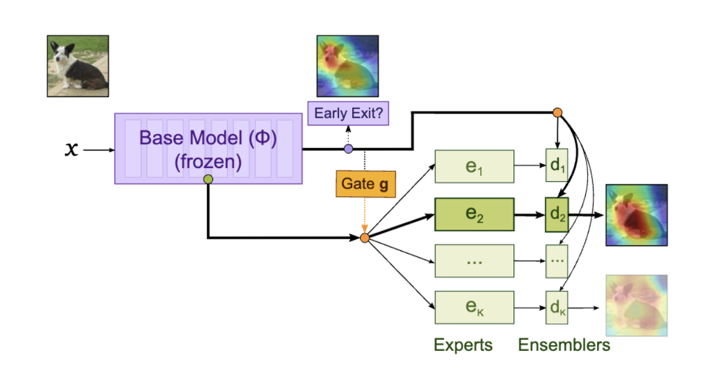
Single-gated mixture-of-experts with early exits

Single-gated MoE

BMVC 2022

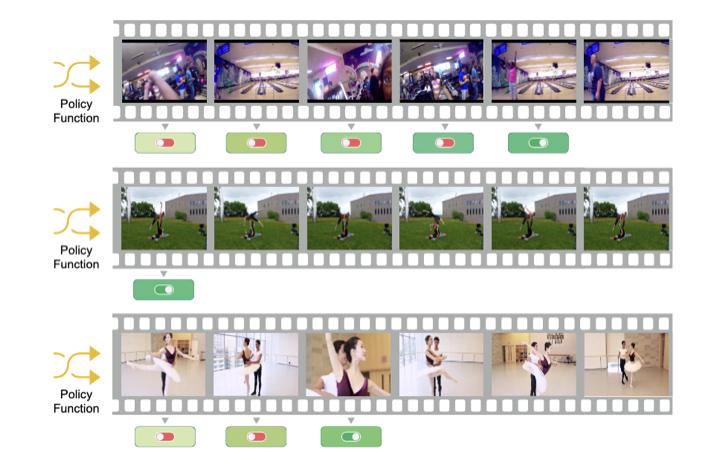
Single-gate Mixture of Experts (MoE) with early exiting for convolutional architectures.
MoE Anytime Inference On-device Early-exiting
FrameExit conditional early-exiting architecture

FrameExit

CVPR 2021 · Oral

Conditional Early Exiting for Efficient Video Recognition.

Early Exiting Video Recognition Gating Network Efficient Recognition
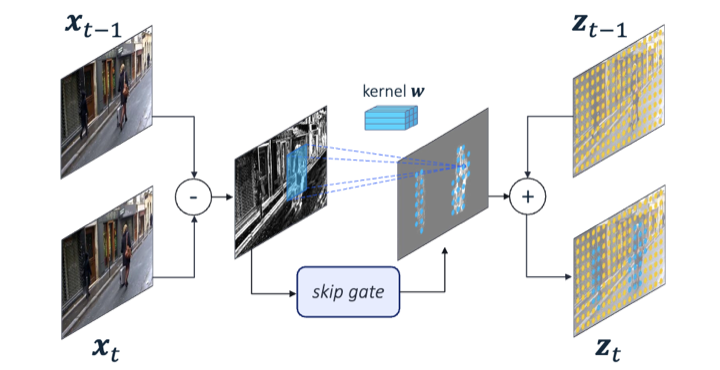
Skip-Convolutions for efficient video processing

SkipConv

CVPR 2021

Skip-Convolutions for efficient video processing.

Residual Convolutions Efficient Video Processing Skip-Convolution
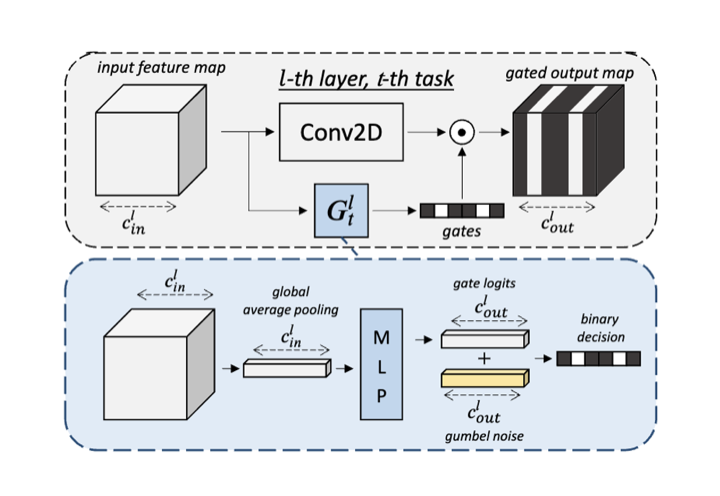
Conditional channel gating for continual learning

Channel Gating for Continual Learning

CVPR 2020 · Oral

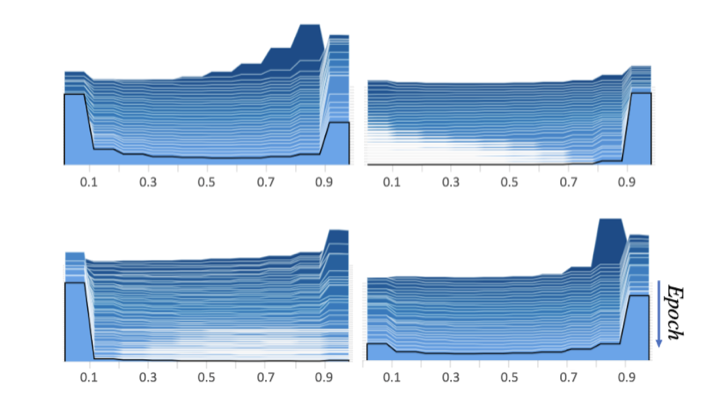
Conditional channel gated networks for task-aware continual learning.
Continual Learning Channel Gating Task-aware Dynamic sparsity
Batch-Shaping for conditional channel-gated networks

Channel Gating with Batch-shaping

ICLR 2020

Batch-shaping for learning conditional channel gated networks.

Batch-shaping Channel Gating Dynamic sparsity